$ rift --summary a.sql b.sql
a: 843633 lines, 67108879 bytes
b: 845034 lines, 67182379 bytes
equal    436 segments, 835632 lines in a, 835632 in b
differs  435 segments, 8001 lines in a, 9402 in b
first differing ranges (0-based, end exclusive):
  a 381..383  b 381..382
  a 1005..1011  b 1004..1010
moved    62 blocks, 2737 lines
  a 21557..21560  b 22434..22437
peak heap 78.6 MiB of 256.0 MiB (82397510 bytes)
time 0.13 s
$
rift-gen --seed 7 --size 64M --profile sql. The page shows 12 selected lines of the full summary. built from 3fcd321, Apple M1, 17 GB RAM, macOS 27.0.1.What it does
Five ways to run Rift. Every output on this page ran on files made by rift-gen --seed 7, and each box says where it shows selected lines of a longer output.
Plain diff and --summary unified diff, then the counts
rift a b writes a unified diff that patch applies to the first file to get the second. --summary counts first, so you know how much differs before you write a diff.
$ rift a.sql b.sql
--- a.sql+++ b.sql@@ -380,7 +380,6 @@ INSERT INTO public.orders (id, customer_id, status, amount, note) VA… 381	178722	cancelled	2930.54	wmojdqnzik INSERT INTO public.orders (id, customer_id, status, amount, note) VA…-383	668107	shipped	5325.74	zu INSERT INTO public.orders (id, customer_id, status, amount, note) VA… 385	359182	cancelled	475.15	ztbyhdlmxk INSERT INTO public.orders (id, customer_id, status, amount, note) VA…
$ rift --summary a.sql b.sql | grep -E "^(a:|b:|equal|differs|peak heap|time)"
a: 843633 lines, 67108879 bytes
b: 845034 lines, 67182379 bytes
equal    436 segments, 835632 lines in a, 835632 in b
differs  435 segments, 8001 lines in a, 9402 in b
peak heap 78.6 MiB of 256.0 MiB (82397510 bytes)
time 0.17 s
Guide: plain diff, --summary.
Key mode rows compared by key, not by position
An export written in a different row order diffs by content, not by position. --key takes a CSV column, an NDJSON field or a pg_dump COPY column, and lists the keys that were added (+), removed (-) or changed (~), with the line of the record in each file.
$ rift --key csv:id a.csv b.csv > keys.txt
$ for k in "~" "-" "+"; do grep -m 2 "^$k" keys.txt; done
$ cut -c1 keys.txt | sort | uniq -c
~6650	6419	6634
~6651	6420	6635
-144	145	-
-145	146	-
+191	-	140
+192	-	141
4024 -
6535 +
5047 ~
Guide: key mode. Use case: compare CSV files by key.
Git rift as the diff driver
Git calls any file over 512 MiB binary and prints no diff. Name the large files in .gitattributes and git runs rift git-diff for them, with git's own headers. It ships in 0.3.0.
$ echo '*.sql diff=rift' >> .gitattributes
$ git config diff.rift.command 'rift git-diff --mem 1G'
$ git diff dump.sql > out.diff
$ head -n 10 out.diff | cut -c1-90
diff --git a/dump.sql b/dump.sqlindex 86d4681..0000000 100644--- a/dump.sql+++ b/dump.sql@@ -380,7 +380,6 @@ INSERT INTO public.orders (id, customer_id, status, amount, note) VALUES (380, 514366, 's 381	178722	cancelled	2930.54	wmojdqnzik INSERT INTO public.orders (id, customer_id, status, amount, note) VALUES (382, 679322, 'c-383	668107	shipped	5325.74	zu INSERT INTO public.orders (id, customer_id, status, amount, note) VALUES (384, 442363, 'n
Guide: git integration. Use case: git says "Binary files differ".
MCP a diff an MCP client can query
rift-mcp lets an MCP client, such as an editor or a chat app, ask about the diff of two huge files without loading them. It has three tools, summary, hunks_at and next_difference, and every answer has a size limit.
$ rift-mcp
-> {"method":"tools/call","params":{"name":"summary","arguments":{"a":"a.sql","b":"b.sql"}}}
<- {
  "a_lines": 843633,
  "b_lines": 845034,
  "differs": {"a_lines":10936,"b_lines":12337,"segments":435},
  "equal": {"a_lines":832697,"b_lines":832697,"segments":435},
  "first_differences": [
    {"a":{"count":9,"start":378},"b":{"count":8,"start":378},"status":"differs"},
    {"a":{"count":21,"start":1006},"b":{"count":21,"start":1005},"status":"differs"},
    ...
  ],
  "mem_budget_bytes": 67108864,
  "more_differences": 415
}
mem, so the counts differ from the CLI's.Guide: MCP server.
VS Code the extension
Compare two huge files from VS Code and open any difference in VS Code's own diff editor.
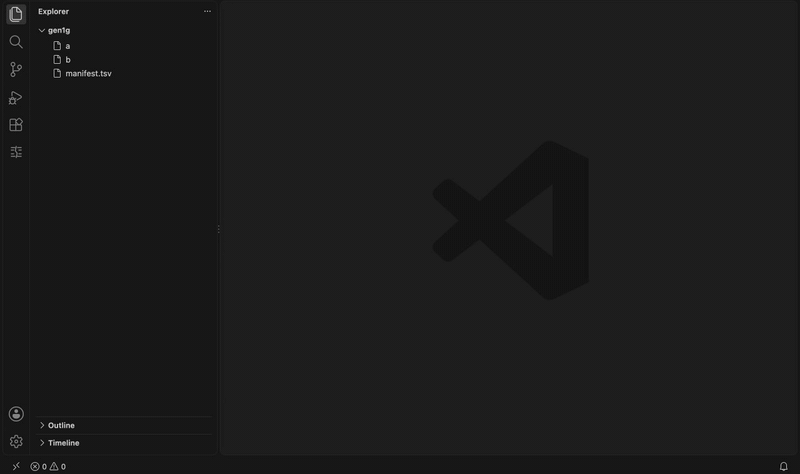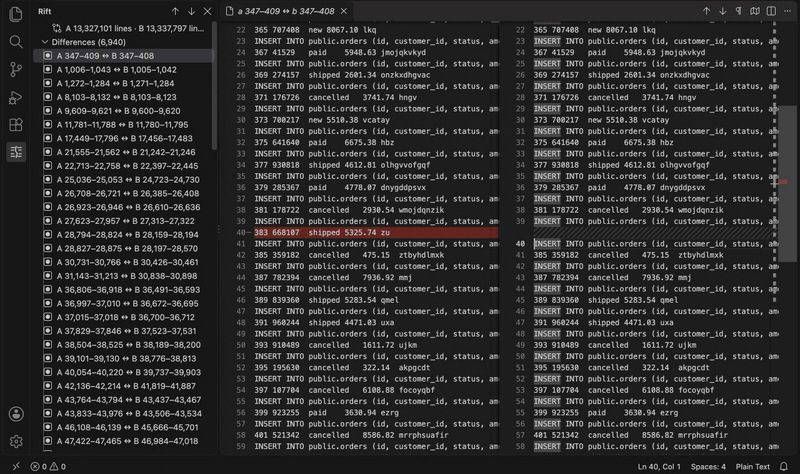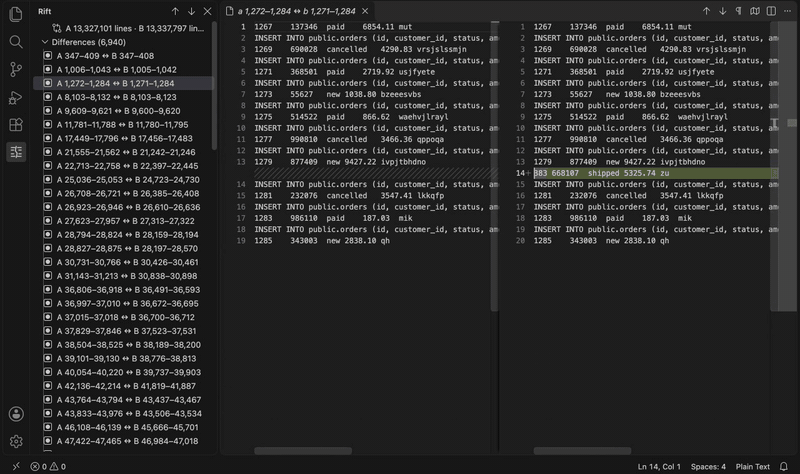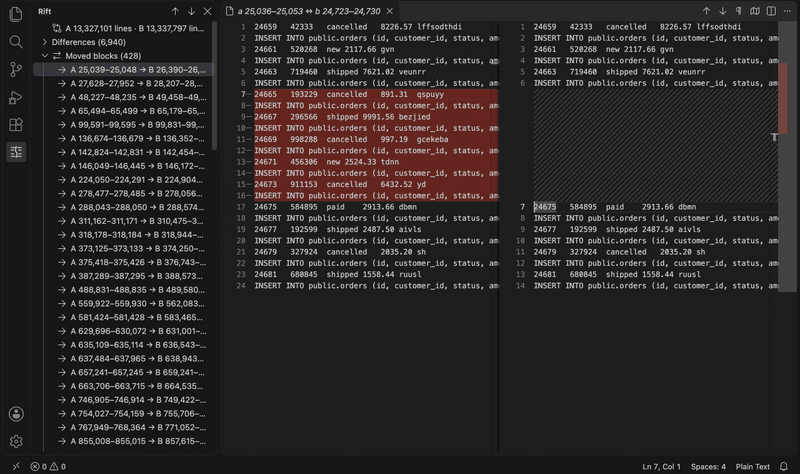
rift-gen --seed 7, on an Apple M1. Also as an MP4.Install from the Marketplace Install from Open VSX
Guide: the VS Code extension.
The file grows. The heap does not.
- input, each of A and B256 MiBeach of A and Bpeak heap83.2 MiBRSS 112.8 MiB, full diff in 0.28 s
- input, each of A and B1 GiBeach of A and Bpeak heap83.6 MiBRSS 113.0 MiB, full diff in 0.69 s
- input, each of A and B2 GiBeach of A and Bpeak heap83.6 MiBRSS 113.4 MiB, full diff in 1.20 s
Rift at --mem 256M on generated SQL pairs, full diff, Intel Core i5-10600, 16 GB RAM, Ubuntu 26.04.1 LTS, files in tmpfs, median of three runs, 2026-11-06. The gauge is the 256 MiB limit; the bar is Rift's own peak heap count. Source: bench/results/linux-intel-core-i5-10600-2026-11-06/report.md. The largest pair measured so far is 10 GiB, on a Mac (see the table below).
What a demo looks like summary, then the terminal view
1 GiB pair, full diff Apple M1
Apple M1, 16 GB RAM, internal SSD, macOS, warm page cache. Source: README.md at the v0.1.0 tag, section Benchmarks. All tables, with commands, are on the benchmarks page.
Apple M1 macOS, warm page cache
| Pair | Tool | Time | Peak memory |
|---|---|---|---|
| 1 GiB | rift --summary | 1.26 s | 127.7 MiB |
| 1 GiB | rift (full diff) | 0.93 s | 130.8 MiB |
| 1 GiB | system diff | 17.55 s | 3.2 GiB |
| 10 GiB | rift --summary | 13.37 s | 136.5 MiB |
| 10 GiB | rift (full diff) | 26.16 s | 136.5 MiB |
| 10 GiB | diff, git diff | did not run: needs more than 16 GB of RAM |
git diff has no 1 GiB row: it treats files over 512 MiB as binary and prints no diff. Peak memory is the resident set; Rift's heap peaked at 83.5 MiB on the 1 GiB pair and 94.1 MiB on the 10 GiB pair.
Intel Core i5-10600 Ubuntu 26.04.1 LTS, tmpfs
| Pair | Tool | Time | Peak memory | Peak heap |
|---|---|---|---|---|
| 256 MiB | rift (full diff) | 0.28 s | 112.8 MiB | 83.2 MiB |
| 256 MiB | GNU diff | 1.62 s | 776.3 MiB | |
| 256 MiB | git diff --no-index | 2.57 s | 1.0 GiB | |
| 1 GiB | rift (full diff) | 0.69 s | 113.0 MiB | 83.6 MiB |
| 1 GiB | GNU diff | killed at the memory cap | ||
| 1 GiB | git diff --no-index | 42.59 s | 5.3 MiB | |
| 2 GiB | rift (full diff) | 1.20 s | 113.4 MiB | 83.6 MiB |
Median of three runs. GNU diff was killed at a 3 GiB cap on the 1 GiB pair. On the 1 GiB pair git diff printed no diff: it treats the files as binary. More rows on the benchmarks page.
What is guaranteed
- The output is a correct edit script: applied to the first file it gives exactly the second, byte for byte.
- A line counts as unchanged only after its bytes are compared. Hashes only propose matches.
- The heap stays at or under
--mem. Files are read withpreadinto fixed buffers, nevermmap. - A region Rift could not refine within the budget is marked approximate in every output.
What is not
- The diff is not minimal.
- A moved block shows in the unified diff as a deletion and an insertion.
--summary,--statsand the terminal view list moved blocks, and detection does not find every block. - Windows is not supported.